Which AI model would you recommend for coding?
- Models
- 14
- Answers
- 230
- Brands named
- 15
Which AI model would you recommend for coding?
14 AI models · 230 answers · ranked by score
ordered by brand score: 100 pts for rank 1 → 20 for rank 5 · no mention = 0
- #1Anthropic90brand score87first choice12345
- #2OpenAI74brand score49first choice
- #3Google52brand score29first choice
- #4DeepSeek25brand score16first choice
- #5Meta13brand score11first choice
Show 10 moreShow less
- #6GitHub13brand score11first choice
- #7Mistral AI9brand score9first choice
- #8Amazon CodeWhisperer6brand score4first choice
- #9Tabnine4brand score2first choice
- #10xAI3brand score3first choice
- #11Replit Ghostwriter3brand score2first choice
- #12Alibaba2brand score1first choice
- #13Microsoft0brand score0first choice
- #14Cursor0brand score0first choice
- #15Sourcegraph Cody0brand score0first choice
Each bar covers the middle half of one model’s answers (Q1–Q3); the line inside it is that model’s median rank for the times it recommended the brand. The badge under a brand says how far apart the models are on it, and “first choice” scores rank 1 far above the rest — a brand can place well overall and still rarely lead an answer.
Swipe left for the full report
Brand by model
Median rank each model gave each brand.
Scroll the table sideways to see every model →
| deepseek-v4.1-flash | gpt-6-astra | gemini-3.8-flash | gemini-3.7-flash | grok-4.6 | qwen3.8-max | claude-opus-5 | gemini-3.5-flash-lite | kimi-k3 | gpt-5.6-luna | gpt-5.6-sol | gpt-5.6-terra | mistral-medium-3.5 | claude-haiku-4.5 | |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Anthropic | 1.0 | 1.0 | 1.0 | 1.0 | 1.0 | 1.0 | 1.0 | 1.0 | 1.0 | 1.0 | 1.0 | 1.0 | — | 2.0 |
| OpenAI | 2.0 | 2.0 | 2.0 | 2.0 | 2.0 | 2.0 | 2.0 | 2.0 | 2.0 | 2.0 | 2.0 | 2.0 | — | 1.0 |
| 3.0 | 3.0 | 4.0 | 4.0 | 3.0 | 3.0 | 3.0 | 3.0 | 3.0 | 3.0 | 3.0 | 3.0 | — | 3.0 | |
| DeepSeek | 4.0 | 4.0 | 3.0 | 3.0 | 4.0 | — | 4.0 | 4.0 | 4.0 | 4.0 | 4.0 | 4.0 | — | — |
| Meta | 5.0 | — | 5.0 | 5.0 | 4.5 | 5.0 | 5.0 | 4.5 | 5.0 | — | — | — | — | 4.0 |
| GitHub | 4.0 | — | — | — | — | 4.0 | 4.0 | — | 4.0 | 4.0 | — | 4.0 | 1.0 | — |
| Mistral AI | 5.0 | 5.0 | 5.0 | 5.0 | 5.0 | 4.5 | 5.0 | 5.0 | — | 5.0 | 5.0 | 5.0 | 5.0 | 5.0 |
| Amazon CodeWhisperer | — | — | — | — | — | — | — | — | — | — | — | — | 2.0 | — |
| Tabnine | — | — | — | — | — | — | — | — | — | — | — | — | 3.0 | — |
| xAI | — | — | — | — | 4.0 | — | — | — | — | — | 5.0 | 5.0 | — | — |
| Replit Ghostwriter | — | — | — | — | — | — | — | — | — | — | — | — | 4.0 | — |
| Alibaba | — | 5.0 | — | — | — | — | 5.0 | — | 5.0 | — | — | — | — | — |
| Microsoft | — | — | — | — | 4.0 | — | — | — | — | 4.0 | — | — | — | — |
| Cursor | — | — | — | — | — | — | — | — | — | 3.0 | — | — | — | — |
| Sourcegraph Cody | — | — | — | — | — | — | — | — | — | — | — | — | 5.0 | — |
A dash means that model never named the brand in any of its runs. Deeper blue is better: rank 1 is the brand a model would recommend first.
Where the models disagree
4 of 15 brands split the panel. Each mark is one model's score for the brand, on the same 0–100 scale as the ranking.
- #6GitHub0100
claude-haiku-4.5 0 → mistral-medium-3.5 100 · 7 of 14 never named it
- #1Anthropic0100
mistral-medium-3.5 0 → qwen3.8-max 100 · 1 of 14 never named it
- #2OpenAI0100
mistral-medium-3.5 0 → claude-haiku-4.5 100 · 1 of 14 never named it
- from here down, the models agree
- #4DeepSeek0100
claude-haiku-4.5 0 → gemini-3.8-flash 50 · 3 of 14 never named it
- #3Google0100
mistral-medium-3.5 0 → claude-haiku-4.5 62 · 1 of 14 never named it
- #5Meta0100
gpt-5.6-luna 0 → claude-haiku-4.5 40 · 5 of 14 never named it
A hollow mark is a model that never named the brand in any of its runs, which scores 0. Agreement is not endorsement — a brand every model ignores equally agrees just as tightly as one they all rank first.
Named, and named first
Across → how frequently the panel names the brand at all.
Up ↑ how often the answers that name it put it first.
- 1Anthropic91/92
- 2OpenAI91/8
- 3Google91/0
- 4DeepSeek60/0
- 5Meta52/0
- 6GitHub20/14
- 7Mistral AI44/0
- 8Amazon CodeWhisperer7/0
The horizontal line sits at 20% — the rate a named brand would lead at if the models were picking one of its 5 slots at random. Above it they are choosing it first on purpose. Both figures average across models, so a thinly sampled model counts the same as a heavily sampled one.
What the models actually said
- Models
- 14
- Answers
- 230
Anthropic leads with a score of 90 of 100, ranked by 13 of 14 models.
The AI models show clear consensus at the top and gradual fragmentation toward the bottom. Anthropic and OpenAI hold the first two positions across nearly all models, Google claims a stable third, and then the field splinters: models diverge sharply on whether to recommend open-weight options, niche products, or simply to stop ranking.
per-model scores 0–100 of 100 · mean 90 across 14 models
Anthropic achieves near-unanimity, with thirteen of fourteen models placing it first and the lone dissenter ranking it second. The panel agrees that Claude dominates repository-scale reasoning, multi-file refactoring, and agentic workflows, drawing heavily on SWE-benchwww.swebench.com×173 and Aider LLM Leaderboardsaider.chat/docs/leaderboards×155 to anchor claims of benchmark leadership and production reliability. The single outlier, claude-haiku-4.5, cites slightly weaker mainstream workflow integration but still rates Anthropic highly.
OpenAI lands in second across most models, recognized for exceptional reasoning and the widest ecosystem reach yet judged narrowly behind on sustained, iterative coding. The split is subtle: models cite the same performance sources but differ on whether raw versatility or task-specific consistency matters more. GitHub Copilot integration and API maturity repeatedly surface as OpenAI's decisive practical edge, even when benchmark gaps favor Claude.
- 100gpt-5.6-terra76
- 100claude-opus-580
- 100gemini-3.5-flash-lite80
- 100gemini-3.7-flash80
- 100gemini-3.8-flash80
- 100gpt-5.6-sol80
- 100gpt-6-astra80
- 100grok-4.680
- 100kimi-k380
- 100qwen3.8-max80
- 80deepseek-v4.1-flash64
- 98gpt-5.6-luna82
- 0mistral-medium-3.50
- 78claude-haiku-4.5100
Anthropic ahead on 12 of 14 models, level on 1
Google's Gemini earns consistent third-place rankings with minimal disagreement. Every model that ranked it emphasized massive context windows as the defining feature, valuable for whole-repository analysis but insufficient to overcome what the panel frames as weaker instruction-following and agentic reliability. Two Gemini models—gemini-3.7-flash and gemini-3.8-flash—rank Google fourth rather than third, a modest self-deprecation that may signal awareness of the gap their own reasoning describes.
Google · 62 points apart on a 0–100 scale
The field fragments beyond the top three. DeepSeek, Meta, and Mistral AI occupy contested middle ground, with models differing on whether open weights, cost efficiency, or self-hosting flexibility warrant inclusion at all. DeepSeek splits models into two camps: those emphasizing value-driven deployment (often placing it fourth) and those focusing on turnkey polish (ranking it lower or omitting it). The divide plausibly traces to whether a model prioritizes developer autonomy or managed convenience, though the data does not confirm this hypothesis directly.
per-model scores 0–50 of 100 · mean 25 across 14 models
GitHub and xAI provoke category confusion. GitHub's brand score of 12.69 hides a stark split: mistral-medium-3.5 ranks it first in every run, while half the panel excludes it entirely. The tension centers on whether Copilot is a model or a product layer over other labs' backends. Models that included GitHub praised workflow integration but noted it "is a router over other labs' models rather than a frontier model itself," making recommendation awkward when the question asks for AI models. xAI faces a similar but milder skepticism, with models acknowledging capable general reasoning but citing thin coding-specific tooling and benchmarks.
GitHub · 100 points apart on a 0–100 scale
Meta and Mistral AI earn broad but lukewarm agreement. Both are framed as strong open-weight options valuable for local deployment, fine-tuning, and privacy-sensitive workflows, yet consistently trailing proprietary leaders on complex tasks. The panel converges on this trade-off without serious dissent, suggesting the open-versus-closed capability gap is accepted across model families. Sources cluster around Hugging Facehuggingface.co×61, Meta AIai.meta.com×43, and Mistral AI documentationdocs.mistral.ai×29, reinforcing the view that these brands excel at democratizing access but not at frontier performance.
The long tail—Amazon CodeWhisperer, Tabnine, Replit Ghostwriter, Alibaba, Microsoft, Cursor, Sourcegraph Cody—receives minimal and highly concentrated attention. Most appear in only one or two models' rankings, and several owe their entire presence to mistral-medium-3.5, which alone ranks CodeWhisperer, Tabnine, Replit, and Sourcegraph. This concentration suggests a hypothesis: models may differ in how they interpret the scope of "AI model" versus "coding tool," with some excluding product layers, IDE extensions, or platform-specific assistants while others include them. The data does not clarify this boundary, but the uneven coverage hints at definitional ambiguity rather than quality consensus.
Alibaba's Qwen models earn respect as top open-weight coding options from the few models that mention them, yet rank last because they "demand more setup work and still lag proprietary leaders on the hardest tasks." Microsoft and Cursor barely register, treated as product wrappers rather than model providers, while Sourcegraph Cody appears once and is dismissed as too immature.
The most frequently recalled sources—SWE-benchwww.swebench.com×173, Aider LLM Leaderboardsaider.chat/docs/leaderboards×155, LMArenalmarena.ai×81—anchor the top-tier consensus, with Anthropic and OpenAI dominating these benchmarks. Google, DeepSeek, and others cite the same leaderboards but are consistently judged to trail. The convergence on these sources suggests the panel shares a common frame for evaluating coding capability, even when downstream recommendations diverge on cost, deployment, or ecosystem fit.
What shaped the answers
239 sources across 3059 references, grouped by site from 802 recalled names. The top 5 carry 37% of them.
Sources are what each model recalled as having shaped its view. It does not mean that the sources were actually used in training. Recalled URLs might also be invalid or hallucinated.
Anthropic
also named Anthropic (Claude), 1. Anthropic, Claude
Summary
Anthropic commands near-universal endorsement across the panel, achieving a brand score of 89.71 and a first choice score of 87.38, with thirteen of fourteen models ranking it and the vast majority placing it first. The models converge tightly on the view that Claude excels at repository-scale reasoning, multi-file refactoring, and agentic coding workflows, consistently citing its leadership on benchmarks such as SWE-benchwww.swebench.com×173 and Aider LLM Leaderboardsaider.chat/docs/leaderboards×155. Themes of careful instruction-following, low hallucination rates, and strong performance in tools like Cursor and Claude Code recur throughout the reasoning, with models emphasizing its suitability for production work where code quality and maintainability matter more than cost.
per-model scores 0–100 of 100 · mean 90 across 14 models
The lone dissenter, claude-haiku-4.5, ranks Anthropic second rather than first, citing strong reasoning and safety but noting it "may be slightly behind GPT-4 in some competitive benchmarks" and "remains slightly less integrated into mainstream development workflows." Every other model places it at the top, often describing Claude as the "default choice," "gold standard," or "premier recommendation" for professional software engineering, with particular praise for handling large codebases, complex debugging, and producing clean, readable implementations. Sources such as Anthropic documentationdocs.anthropic.com×19 and LMSYS Chatbot Arenachat.lmsys.org×70 reinforce the perception of technical strength backed by both benchmark results and developer community sentiment.
“Claude models (Sonnet/Opus 4.x) lead agentic coding benchmarks like SWE-bench Verified and are the default engine behind many coding tools, including Cursor and GitHub Copilot's agent modes, excelling at large-codebase work and multi-file refactors in real-world development.”
“Anthropic's Claude 3.5 Sonnet is widely regarded by developers as the gold standard for coding assistants due to its exceptional reasoning capabilities and deep understanding of complex codebases.”
Per model summary
- claude-opus-5
- brand score
- 100
- first choice
- 100
- median rank
- 1.0
- present in
- 25/25
Claude models (Sonnet/Opus 4.x) lead agentic coding benchmarks like SWE-bench Verified and serve as the default engine behind major coding tools, excelling at large-codebase work and multi-file refactors in real-world development.
- deepseek-v4.1-flash
- brand score
- 80
- first choice
- 80
- median rank
- 1.0
- present in
- 8/10
Claude models are valued for careful instruction-following and strong performance on complex refactors, debugging, and agentic coding workflows, making them a practical default choice for serious development work despite not always leading on raw benchmarks.
- gemini-3.5-flash-lite
- brand score
- 100
- first choice
- 100
- median rank
- 1.0
- present in
- 10/10
Claude models, particularly Claude 3.5 Sonnet, have established a gold standard in AI-assisted development through exceptional reasoning capabilities, deep contextual understanding, and consistent superiority in generating clean, accurate code across complex software engineering tasks.
- gemini-3.7-flash
- brand score
- 100
- first choice
- 100
- median rank
- 1.0
- present in
- 25/25
Anthropic models, particularly Claude 3.5 Sonnet, consistently lead industry benchmarks and developer preference for code generation, excelling at large-codebase comprehension, precise refactoring, and producing clean code with minimal hallucinations.
- gemini-3.8-flash
- brand score
- 100
- first choice
- 100
- median rank
- 1.0
- present in
- 10/10
Anthropic models lead the industry in complex software engineering benchmarks like SWE-bench, excelling at nuanced instruction-following, multi-file refactoring, and producing clean code with remarkably low hallucination rates, making them the premier choice for professional coding workflows.
- gpt-5.6-luna
- brand score
- 98
- first choice
- 95
- median rank
- 1.0
- present in
- 20/20
Anthropic's Claude models are top recommendations for understanding large codebases, following detailed instructions, and performing multi-file refactors, with consistent strength in debugging and producing readable, maintainable code.
- gpt-5.6-sol
- brand score
- 100
- first choice
- 100
- median rank
- 1.0
- present in
- 20/20
Anthropic is the top recommendation for understanding large codebases, making precise multi-file edits, and handling agentic software-engineering workflows, with strong coding-focused tooling and broad integration making it practical for serious development work.
- gpt-5.6-terra
- brand score
- 100
- first choice
- 100
- median rank
- 1.0
- present in
- 20/20
Anthropic is the top recommendation for demanding coding work due to Claude models' strength in repository-scale reasoning, code review, debugging, and following detailed engineering constraints, particularly when code quality and careful explanations matter more than cost.
- gpt-6-astra
- brand score
- 100
- first choice
- 100
- median rank
- 1.0
- present in
- 25/25
Anthropic is the default recommendation for general-purpose coding, particularly valued for understanding unfamiliar repositories, making coordinated multi-file changes, and providing clear explanations, with agentic development tooling making it especially suited for substantial software-engineering work.
- grok-4.6
- brand score
- 100
- first choice
- 100
- median rank
- 1.0
- present in
- 10/10
Anthropic's Claude models, especially 3.5 Sonnet, consistently lead coding benchmarks with superior reasoning, large context windows for handling entire codebases, and reliable code generation with fewer hallucinations, making them the strongest overall choice for professional development.
- kimi-k3
- brand score
- 100
- first choice
- 100
- median rank
- 1.0
- present in
- 25/25
Claude models consistently top real-world coding benchmarks like SWE-bench Verified and are widely praised by developers for code quality, multi-file reasoning, and agentic coding capabilities, making them the go-to choice for professional software development work.
- qwen3.8-max
- brand score
- 100
- first choice
- 100
- median rank
- 1.0
- present in
- 10/10
Claude models are valued as the top choice for coding due to strength in understanding large codebases, following complex multi-step instructions carefully, and producing coherent multi-file edits with careful attention to safety and maintainability in real development workflows.
- claude-haiku-4.5
- brand score
- 78
- first choice
- 48
- median rank
- 2.0
- present in
- 10/10
Claude models consistently emphasize strong reasoning abilities, code safety, and thoughtful explanations, with particular strength in handling large context windows for complex projects and code reviews.
Sources per model
Each model’s own references for this brand, grouped by site. Tile area is that site’s share of the model’s references; tap one for the pages behind it.
anthropic.com
- ×3/claude
- ×2Anthropic /
- ×2Anthropic Claude 3.5 Sonnet /news/claude-3-5-sonnet
anthropic.com
- ×9/engineering/claude-code-best-practices
- ×5Anthropic — Claude 3.5 Sonnet /news/claude-3-5-sonnet
- ×3Anthropic — Claude /claude
- ×2Anthropic engineering /engineering
- ×2Anthropic — Claude 3.7 Sonnet and Claude Code /news/claude-3-7-sonnet
- ×1Anthropic — Claude Code /claude-code
docs.anthropic.com
- ×9/
- ×1Anthropic Models documentation /en/docs/about-claude/models
Sources are what each model recalled as having shaped its view. It does not mean that the sources were actually used in training. Recalled URLs might also be invalid or hallucinated.
OpenAI
also named OpenAI (GPT/Codex), 2. OpenAI, GPT, OpenAI (GPT / o-series / Codex), OpenAI (GPT/Codex/o-series)
Summary
OpenAI commands a strong position in the coding AI landscape with a brand score of 74.43 and first choice score of 49.46, appearing in the rankings of 13 of 14 models. The panel's assessment reveals significant divergence: one model awarded it a perfect 100 for consistent first-place rankings, while another gave it zero, yielding a standard deviation of 21.78 that the study labels "models split." Most evaluators placed OpenAI second, recognizing its GPT-4, GPT-4o, and o-series reasoning models as highly capable across code generation, debugging, and algorithmic problem-solving, yet narrowly trailing Anthropic's Claude for sustained, repository-level work. The consensus holds that OpenAI offers the most mature ecosystem—powering GitHub Copilot×3 and delivering broad API, IDE, and tooling integrations—even when competitors edge ahead on specialized benchmarks or long agentic coding sessions.
per-model scores 0–100 of 100 · mean 74 across 14 models
The reasoning behind OpenAI's strong but not dominant standing centers on three themes: exceptional reasoning and versatility, unmatched ecosystem maturity, and narrow performance gaps in specialized tasks. Models praised its advanced reasoning capabilities on competitive programming and complex algorithms, citing SWE-bench×3 and LMSYS Chatbot Arenachat.lmsys.org×70 as evidence of robust general-purpose performance. At the same time, evaluators noted variability by model version and occasional verbosity, with several pointing out that Claude feels more consistent for iterative, multi-file edits. The ecosystem argument—anchored by GitHub Copilot integration, extensive API documentation, and the widest developer adoption—repeatedly emerged as OpenAI's decisive practical advantage, even when raw coding scores fell slightly short of the leader.
“OpenAI's GPT-4 and GPT-4o models have demonstrated exceptional coding capabilities with strong performance on competitive programming benchmarks and real-world development tasks.”
“GPT-5 class and the o-series reasoning models are excellent at algorithmic problem solving, debugging, and competitive-programming-style tasks, with Codex/Codex CLI providing a solid agentic coding workflow.”
Per model summary
- claude-haiku-4.5
- brand score
- 100
- first choice
- 100
- median rank
- 1.0
- present in
- 10/10
GPT-4 and GPT-4o models consistently demonstrate exceptional coding capabilities with strong competitive programming benchmark performance, and their integration with GitHub Copilot has established industry-standard adoption among developers.
- claude-opus-5
- brand score
- 80
- first choice
- 50
- median rank
- 2.0
- present in
- 25/25
GPT-5-class and o-series reasoning models excel at algorithmic problem solving and competitive programming tasks, supported by the broadest ecosystem, API maturity, and tooling integrations in the industry.
- deepseek-v4.1-flash
- brand score
- 64
- first choice
- 40
- median rank
- 2.0
- present in
- 8/10
GPT and Codex models are strong general coding assistants with broad language coverage and deep ecosystem support, ranking as a very close second with mature API availability and widespread IDE integrations.
- gemini-3.5-flash-lite
- brand score
- 80
- first choice
- 50
- median rank
- 2.0
- present in
- 10/10
OpenAI remains a powerhouse through GPT-4 series models that offer robust multi-language support and seamless integration into major developer tools like GitHub Copilot, maintaining reliability despite being edged out in some recent nuanced coding benchmarks.
- gemini-3.7-flash
- brand score
- 80
- first choice
- 50
- median rank
- 2.0
- present in
- 25/25
OpenAI provides industry-standard coding capabilities with powerful reasoning models and the deepest integration into the widest developer ecosystem, maintaining exceptional reliability across complex algorithmic tasks despite tight competition.
- gemini-3.8-flash
- brand score
- 80
- first choice
- 50
- median rank
- 2.0
- present in
- 10/10
OpenAI delivers industry-leading reasoning and code generation with deep integration across developer ecosystems and popular IDE extensions, though occasionally requiring more iterative prompting or showing less consistency than top rivals on large-scale refactoring.
- gpt-5.6-luna
- brand score
- 82
- first choice
- 55
- median rank
- 2.0
- present in
- 20/20
OpenAI offers highly capable general-purpose models with strong performance across code generation, debugging, and tool-assisted workflows, ranking just behind Anthropic because coding quality can vary by model and task.
- gpt-5.6-sol
- brand score
- 80
- first choice
- 50
- median rank
- 2.0
- present in
- 20/20
OpenAI offers excellent code generation, reasoning, debugging, and tool use backed by a mature API and extensive developer ecosystem, ranking just below Anthropic because performance varies by model and workflow.
- gpt-5.6-terra
- brand score
- 76
- first choice
- 48
- median rank
- 2.0
- present in
- 19/20
OpenAI is an excellent general-purpose coding choice with strong reasoning models and mature API tooling, ranking just behind Anthropic because the best choice depends heavily on specific codebases, tasks, and workflow requirements.
- gpt-6-astra
- brand score
- 80
- first choice
- 50
- median rank
- 2.0
- present in
- 25/25
OpenAI is a close second offering strong all-round coding capabilities, debugging, and reasoning, particularly appealing for its broad developer ecosystem and API integrations that support both software development and broader technical workflows.
- grok-4.6
- brand score
- 80
- first choice
- 50
- median rank
- 2.0
- present in
- 10/10
OpenAI models power widely adopted tools like GitHub Copilot and deliver versatile, high-quality coding performance across languages, benefiting from a mature ecosystem and extensive training data despite trailing slightly on some recent specialized evaluations.
- kimi-k3
- brand score
- 80
- first choice
- 50
- median rank
- 2.0
- present in
- 25/25
OpenAI's GPT and o-series models deliver excellent coding performance with the broadest ecosystem adoption including GitHub Copilot integration, though recent benchmarks often place them slightly behind Anthropic on complex software engineering tasks.
- qwen3.8-max
- brand score
- 80
- first choice
- 50
- median rank
- 2.0
- present in
- 10/10
OpenAI's GPT models are highly capable, versatile coding assistants with strong general reasoning and a mature ecosystem of APIs and developer tools, ranking second because they are slightly less consistent than Claude for complex repository-level edits.
Sources per model
Each model’s own references for this brand, grouped by site. Tile area is that site’s share of the model’s references; tap one for the pages behind it.
openai.com
- ×13/index/introducing-codex
- ×2OpenAI — Introducing GPT-4.1 /index/gpt-4-1
- ×1OpenAI — Introducing GPT-4.1 /index/introducing-gpt-4-1
openai.com
- ×7/research
- ×1OpenAI Benchmark Reports /index/learning-to-reason-with-llms
platform.openai.com
- ×5/docs
- ×4OpenAI Models documentation /docs/models
- ×1OpenAI Platform /
- ×1OpenAI API reference /docs/api-reference
openai.com
- ×4/codex
- ×4OpenAI Codex /index/introducing-codex
- ×3/
- ×2/coding
- ×2/solutions/coding
- ×1/index/introducing-o3-mini
- ×1OpenAI Research /research
platform.openai.com
- ×12/docs/overview
- ×4OpenAI models /docs/models
- ×3/docs
Sources are what each model recalled as having shaped its view. It does not mean that the sources were actually used in training. Recalled URLs might also be invalid or hallucinated.
also named Google (Gemini), Google DeepMind, Google DeepMind (Gemini), 3. Google, Gemini
Summary
Google achieves a brand score of 52.33 across the panel, with per-model scores spanning 0 to 62 and broad agreement among the models. Every model except one ranked Google, and none placed it first. The consistent theme is that Google's Gemini models offer exceptional long-context capabilities—often cited as industry-leading context windows of one to two million tokens—that make them uniquely valuable for analyzing entire repositories, extensive documentation, and large-scale refactoring tasks. Models repeatedly note tight integration with Google Cloud, Android Studio, and the broader Google developer ecosystem, alongside competitive pricing and generous free tiers via AI Studio and Gemini CLI. However, the panel uniformly agrees that while Gemini is highly capable, its code generation precision, instruction-following consistency, and agentic coding reliability trail Anthropic and OpenAI on complex multi-step tasks. Sources underpinning this view include Google DeepMind Gemini model pagedeepmind.google/technologies/gemini×19, SWE-benchwww.swebench.com×173, and Aider LLM Leaderboardsaider.chat/docs/leaderboards×155.
The models frame Google as especially attractive for niche workflows—large codebase analysis, multimodal tasks involving diagrams or UI screenshots, and environments already standardized on Google Cloud—but not as the default choice for general-purpose coding assistance. Developer mindshare and ecosystem maturity are noted as weaker than the top two, and several models caution that coding output may require more manual refinement or validation. Despite these reservations, Gemini is recognized as rapidly improving and highly competitive on benchmarks, making it a strong third option and occasionally the best fit when context length or Google integration is the priority.
“Gemini 2.5/3 Pro's massive context window excels at repository-wide reasoning and offers strong value through free tiers, though it slightly trails Claude and GPT in agentic code-editing reliability.”
“Gemini models offer strong coding with industry-leading context windows valuable for large codebases, but developer mindshare and consistency on multi-step work trail Anthropic and OpenAI.”
Per model summary
- claude-haiku-4.5
- brand score
- 62
- first choice
- 35
- median rank
- 3.0
- present in
- 10/10
Gemini models provide solid coding capabilities and integrate well with Google's ecosystem, but consistently lag behind top competitors in specialized coding benchmarks and developer adoption.
- claude-opus-5
- brand score
- 60
- first choice
- 33
- median rank
- 3.0
- present in
- 25/25
Gemini 2.5/3 Pro's massive context window excels at repository-wide reasoning and offers strong value through free tiers, though it slightly trails Claude and GPT in agentic code-editing reliability.
- deepseek-v4.1-flash
- brand score
- 48
- first choice
- 27
- median rank
- 3.0
- present in
- 8/10
Gemini models are highly capable with strong long-context and multimodal abilities, but their agentic coding polish and developer ecosystem consistency lag behind Anthropic and OpenAI.
- gemini-3.5-flash-lite
- brand score
- 60
- first choice
- 33
- median rank
- 3.0
- present in
- 10/10
Gemini's massive context windows enable unmatched whole-repository analysis and refactoring, though code generation precision occasionally lags behind top-tier competitors.
- gpt-5.6-luna
- brand score
- 58
- first choice
- 33
- median rank
- 3.0
- present in
- 20/20
Google models are strong for large-context workflows and ecosystem integration, but coding quality and consistency vary more by version and environment than the top two alternatives.
- gpt-5.6-sol
- brand score
- 60
- first choice
- 33
- median rank
- 3.0
- present in
- 20/20
Gemini models offer strong coding with large context windows and cloud integration, but their coding precision and consistency across model tiers feel less reliable than the top two choices.
- gpt-5.6-terra
- brand score
- 57
- first choice
- 32
- median rank
- 3.0
- present in
- 19/20
Gemini models excel at large-context tasks and Google Cloud integration, but coding quality and tooling fit vary more by model version and workflow than the top two options.
- gpt-6-astra
- brand score
- 60
- first choice
- 33
- median rank
- 3.0
- present in
- 25/25
Gemini is especially attractive for large-context coding tasks involving extensive documentation or repositories, ranking third generally but potentially first when long-context analysis is the priority.
- grok-4.6
- brand score
- 60
- first choice
- 33
- median rank
- 3.0
- present in
- 10/10
Gemini models offer very large context windows and solid multimodal coding support with good Google ecosystem integration, but trail the top two in raw coding accuracy on independent benchmarks.
- kimi-k3
- brand score
- 60
- first choice
- 33
- median rank
- 3.0
- present in
- 25/25
Gemini models offer strong coding performance with industry-leading context windows valuable for large codebases, but developer mindshare and consistency on multi-step work trail Anthropic and OpenAI.
- qwen3.8-max
- brand score
- 56
- first choice
- 32
- median rank
- 3.0
- present in
- 10/10
Gemini models offer strong coding with very large context windows and Google ecosystem integration, but coding consistency feels less reliable than the top two across everyday tasks.
- gemini-3.7-flash
- brand score
- 46
- first choice
- 27
- median rank
- 4.0
- present in
- 25/25
Gemini's industry-leading context windows allow simultaneous processing of entire repositories and documentation, though generated code occasionally requires more manual refinement than top competitors.
- gemini-3.8-flash
- brand score
- 46
- first choice
- 28
- median rank
- 4.0
- present in
- 10/10
Gemini's massive context windows enable effortless ingestion of entire multi-million token codebases, though code generation consistency on complex logic and edge cases occasionally trails Anthropic or OpenAI.
Sources per model
Each model’s own references for this brand, grouped by site. Tile area is that site’s share of the model’s references; tap one for the pages behind it.
ai.google.dev
- ×5/
- ×1Google AI for Developers Gemini API docs /gemini-api/docs
- ×1Gemini API Models /gemini-api/docs/models
ai.google.dev
- ×22/gemini-api/docs
- ×10Google — Gemini long-context documentation /gemini-api/docs/long-context
deepmind.google
- ×16/
- ×5Google DeepMind Blog /discover/blog
- ×2Google DeepMind Research /research
- ×1/technologies/gemini
ai.google.dev
- ×7/
- ×3Gemini API documentation /gemini-api/docs
- ×1Gemini models documentation /gemini-api/docs/models
cloud.google.com
- ×10/gemini/docs/codeassist/overview
- ×3Google Cloud Vertex AI /vertex-ai
- ×1/gemini/code-assist
- ×1Google Cloud /vertex-ai/generative-ai/docs/code/code-models-overview
ai.google.dev
- ×10/gemini-api/docs
- ×6Google AI for Developers /
- ×3Gemini API model documentation /gemini-api/docs/models
ai.google.dev
- ×10/
- ×9Gemini API documentation /gemini-api/docs
- ×2/gemini-api/docs/models
no URL recalled
- ×4named without a URL
Sources are what each model recalled as having shaped its view. It does not mean that the sources were actually used in training. Recalled URLs might also be invalid or hallucinated.
DeepSeek
also named DeepSeek (DeepSeek-Coder/V3)
Summary
DeepSeek scores consistently across the panel, earning a brand score of 25 and appearing in 11 of 14 models' rankings, though never in first place. The models converge on a narrow assessment: DeepSeek occupies a value-driven niche, offering strong coding performance through open-weight models at dramatically lower cost than proprietary alternatives, but with less mature enterprise tooling and ecosystem polish. Every model that ranked it placed it fourth or fifth, and the standard deviation of 17.79 reflects broad agreement on both its strengths and limitations.
per-model scores 0–50 of 100 · mean 25 across 14 models
The recurring theme is cost efficiency paired with deployment flexibility. Models repeatedly cite DeepSeek's open weights, self-hosting options, and competitive pricing as core appeals, often drawing on Hugging Facehuggingface.co×22, DeepSeek GitHubgithub.com/deepseek-ai×25, and Aider LLM Leaderboardsaider.chat/docs/leaderboards×155. The trade-off is consistent: while benchmark performance rivals frontier labs on code synthesis and algorithmic tasks, DeepSeek trails in enterprise support, IDE integrations, and agentic reliability. Models frame it as the default recommendation for budget-conscious teams, privacy-sensitive workflows, or high-volume use cases where hosting control matters, but not for organizations prioritizing polished managed services or the most complex multi-step coding agents.
“DeepSeek delivers state-of-the-art open-weight coding models that rival top proprietary offerings at a fraction of the inference cost, making it a premier choice for cost-conscious developers and self-hosted environments.”
“DeepSeek is an appealing option when cost efficiency and access to open-weight models matter, but realizing those advantages requires more attention to deployment, tooling, and model selection than the more polished alternatives.”
Per model summary
- gemini-3.7-flash
- brand score
- 49
- first choice
- 28
- median rank
- 3.0
- present in
- 22/25
DeepSeek delivers state-of-the-art open-weight coding models that rival top proprietary offerings at a fraction of the inference cost, making it a premier choice for cost-conscious developers and self-hosted environments.
- gemini-3.8-flash
- brand score
- 50
- first choice
- 28
- median rank
- 3.0
- present in
- 9/10
DeepSeek provides state-of-the-art coding performance that rivals top proprietary models at disruptive cost points with open-weight options, though its ecosystem tooling and platform maturity trail established commercial leaders.
- claude-opus-5
- brand score
- 37
- first choice
- 24
- median rank
- 4.0
- present in
- 25/25
DeepSeek's V3 and R1-lineage models deliver near-frontier coding performance at dramatically lower cost with open weights, making them the best value for budget-conscious or self-hosting teams, though they lag top proprietary labs on complex agentic tasks and tooling polish.
- deepseek-v4.1-flash
- brand score
- 28
- first choice
- 18
- median rank
- 4.0
- present in
- 7/10
DeepSeek offers strong price-performance and open-weight options attractive for cost-sensitive or self-hosted coding workflows, though its tooling, enterprise support, and coding-assistant ecosystem are less mature than top proprietary alternatives.
- gemini-3.5-flash-lite
- brand score
- 22
- first choice
- 15
- median rank
- 4.0
- present in
- 6/10
DeepSeek has emerged as a disruptive force offering open-weight models that punch well above their weight class in coding benchmarks at a fraction of the cost, though enterprise trust and adoption are still maturing.
- gpt-5.6-luna
- brand score
- 13
- first choice
- 9
- median rank
- 4.0
- present in
- 7/20
DeepSeek offers capable coding models at comparatively low cost with attractive open-weight availability, but reliability, hosted-service availability, and tooling consistency may be less predictable than leading commercial providers.
- gpt-5.6-sol
- brand score
- 40
- first choice
- 25
- median rank
- 4.0
- present in
- 20/20
DeepSeek provides strong coding performance at highly competitive prices with valuable open-weight and self-hosting options, though its enterprise support, integrations, and operational ecosystem are less mature than larger commercial providers.
- gpt-5.6-terra
- brand score
- 31
- first choice
- 21
- median rank
- 4.0
- present in
- 17/20
DeepSeek is a compelling value-oriented option offering strong coding performance with open-weight availability and deployment flexibility, though its enterprise tooling, support, and integration maturity are generally less comprehensive than leading proprietary platforms.
- gpt-6-astra
- brand score
- 38
- first choice
- 25
- median rank
- 4.0
- present in
- 25/25
DeepSeek is an appealing option when cost efficiency and access to open-weight models matter, but realizing those advantages requires more attention to deployment, tooling, and model selection than the more polished alternatives.
- grok-4.6
- brand score
- 4
- first choice
- 3
- median rank
- 4.0
- present in
- 1/10
DeepSeek achieves impressive benchmark scores matching larger proprietary systems at lower cost with openly available weights, though it is newer with less extensive production-tooling and enterprise validation than established leaders.
- kimi-k3
- brand score
- 38
- first choice
- 25
- median rank
- 4.0
- present in
- 25/25
DeepSeek delivers impressive coding performance at a fraction of the cost with strong open-weight models, making it excellent for budget-conscious and self-hosting teams, though its ecosystem tooling and enterprise maturity lag larger established providers.
Sources per model
Each model’s own references for this brand, grouped by site. Tile area is that site’s share of the model’s references; tap one for the pages behind it.
github.com
- ×3/deepseek-ai/DeepSeek-Coder
- ×1DeepSeek GitHub /deepseek-ai
- ×1DeepSeek-R1 GitHub /deepseek-ai/DeepSeek-R1
github.com
- ×20/deepseek-ai/DeepSeek-Coder
- ×12DeepSeek — DeepSeek-Coder-V2 /deepseek-ai/DeepSeek-Coder-V2
- ×10DeepSeek-V3 repository /deepseek-ai/DeepSeek-V3
- ×4DeepSeek — DeepSeek-R1 /deepseek-ai/DeepSeek-R1
huggingface.co
- ×3/
- ×1Hugging Face Leaderboards /spaces
- ×1Hugging Face Leaderboards /spaces/open-llm-leaderboard/open_llm_leaderboard
huggingface.co
- ×14/
- ×3Hugging Face Models /deepseek-ai
- ×2Hugging Face Leaderboards /spaces/open-llm-leaderboard/open_llm_leaderboard
- ×1Hugging Face Leaderboards /spaces
no URL recalled
- ×1named without a URL
github.com
- ×11/deepseek-ai
- ×2DeepSeek-V3 GitHub repository /deepseek-ai/DeepSeek-V3
- ×1DeepSeek-R1 GitHub repository /deepseek-ai/DeepSeek-R1
Sources are what each model recalled as having shaped its view. It does not mean that the sources were actually used in training. Recalled URLs might also be invalid or hallucinated.
Meta
also named Meta (Llama), Meta (Llama/Code Llama), 5. Meta, Llama
Summary
Meta's Llama models earn a modest position in the coding recommendation landscape, with a brand score of 13.46 and broad agreement among evaluators—nine of fourteen models ranked it, though none placed it first. The consensus view treats Llama as a strong open-weights foundation valued for local deployment, privacy-sensitive workflows, and fine-tuning flexibility, but one that consistently trails proprietary frontier models on out-of-the-box coding performance and ease of use. Models frequently cite Hugging Facehuggingface.co×61 and Meta AIai.meta.com×43 when discussing the open ecosystem, customization potential, and community-driven development that define Meta's offering, while also noting that complex coding tasks typically require more setup, prompt engineering, or fine-tuning than specialized commercial alternatives deliver.
Meta · 40 points apart on a 0–100 scale
The divide in recommendations centers on what developers prioritize: control and transparency versus turnkey capability. Evaluators uniformly praise Llama for democratizing access to capable coding assistance, enabling complete data sovereignty, and serving as the backbone for self-hosted and privacy-compliant enterprise deployments. Yet that same consensus acknowledges the models generally underperform leaders like Claude, GPT, and Gemini on demanding benchmarks and agentic reasoning tasks, positioning Meta as the premier choice when openness, customization, or local hosting outweighs raw coding accuracy, but a secondary option when developers seek polished, hosted assistance for complex software engineering work.
“Meta's Llama models are valuable open-weight options for teams needing full control, local deployment, and fine-tuning capability, but out-of-the-box coding performance generally lags behind frontier proprietary models and requires more setup effort.”
“Llama models are the premier open-weights option enabling local, private deployment with complete data control and fine-tuning flexibility, but out-of-the-box coding performance generally requires more prompt tuning or compute than specialized proprietary models.”
Per model summary
- claude-haiku-4.5
- brand score
- 40
- first choice
- 25
- median rank
- 4.0
- present in
- 10/10
Llama models are open-source and useful for local or customized deployments, but consistently underperform leading proprietary models on coding benchmarks and require more setup or fine-tuning to match top-tier alternatives.
- gemini-3.5-flash-lite
- brand score
- 30
- first choice
- 23
- median rank
- 4.5
- present in
- 10/10
Llama models provide solid open-source foundations for local, privacy-focused coding assistance with unmatched customization potential, but generally require significant setup and fine-tuning to match the out-of-the-box performance of proprietary alternatives.
- grok-4.6
- brand score
- 30
- first choice
- 23
- median rank
- 4.5
- present in
- 10/10
Llama models are strong open-source alternatives that can be run locally, fine-tuned, and deployed privately with cost advantages, but generally trail leading closed-source frontier models on demanding coding benchmarks and out-of-the-box ease of use.
- claude-opus-5
- brand score
- 10
- first choice
- 10
- median rank
- 5.0
- present in
- 12/25
Llama models are valuable for open-weight, on-premise deployment and fine-tuning with strong community support, but recent releases have fallen behind both proprietary frontier models and Chinese open-weight competitors on coding benchmarks.
- deepseek-v4.1-flash
- brand score
- 12
- first choice
- 12
- median rank
- 5.0
- present in
- 6/10
Llama models are important open-weight options valuable for customization, local deployment, and privacy-sensitive environments, but generally trail top proprietary models in out-of-the-box coding performance on complex tasks.
- gemini-3.7-flash
- brand score
- 13
- first choice
- 13
- median rank
- 5.0
- present in
- 16/25
Llama models are the premier open-weights option enabling local, private deployment with complete data control and fine-tuning flexibility, but out-of-the-box coding performance generally requires more prompt tuning or compute than specialized proprietary models.
- gemini-3.8-flash
- brand score
- 16
- first choice
- 15
- median rank
- 5.0
- present in
- 7/10
Meta leads in open-source innovation, providing models that offer complete privacy, customization, and local hosting flexibility, but generally require significant setup and trail dedicated proprietary APIs in out-of-the-box coding precision on complex tasks.
- kimi-k3
- brand score
- 16
- first choice
- 16
- median rank
- 5.0
- present in
- 20/25
Llama models are valuable open-weight options for teams needing full control, local deployment, and fine-tuning capability, but out-of-the-box coding performance generally lags behind frontier proprietary models and requires more setup effort.
- qwen3.8-max
- brand score
- 22
- first choice
- 21
- median rank
- 5.0
- present in
- 10/10
Llama models are valuable open-weight options for self-hosting, customization, and privacy-sensitive coding workflows where control matters, but generally require more setup and trail top proprietary models for out-of-the-box coding quality on complex tasks.
Sources per model
Each model’s own references for this brand, grouped by site. Tile area is that site’s share of the model’s references; tap one for the pages behind it.
ai.meta.com
- ×4/llama
- ×2Code Llama /blog/code-llama-large-language-model-coding
- ×1Meta AI /
- ×1Meta AI Blog /blog
huggingface.co
- ×3/
- ×3Hugging Face Open LLM Leaderboard /spaces/open-llm-leaderboard/open_llm_leaderboard
- ×1Hugging Face Leaderboards /spaces
huggingface.co
- ×8/
- ×2/meta-llama
- ×1Open LLM Leaderboard /spaces/open-llm-leaderboard/open_llm_leaderboard
huggingface.co
- ×5/spaces/open-llm-leaderboard/open_llm_leaderboard
- ×3Hugging Face Open LLM / BigCode leaderboards /spaces/bigcode/bigcode-models-leaderboard
- ×2Hugging Face model hub /meta-llama
- ×1Hugging Face Open LLM discussions /
- ×1Hugging Face Open LLM / BigCode models leaderboards /spaces
no URL recalled
- ×3named without a URL
Sources are what each model recalled as having shaped its view. It does not mean that the sources were actually used in training. Recalled URLs might also be invalid or hallucinated.
How this was measured
The question
- Unaided brand recommendation question: “Which AI model would you recommend for coding?”
- The prompt asks each model to return exactly 5 brands, ranked 1 to 5, and for each one a reason for the recommendation and the sources that informed it.
Sampling
- Models are not deterministic, so the question is asked over and over — 16 answers per model
- Spellings of the same brand are normalized to the most commonly used form before counting
Measures of Position: Median and Quartiles
- Median value indicates that in 50% of answers the brand held this position or higher.
- Quartiles help visualize the spread of rankings per brand. Q1 indicates that 25% of answers had this rank or higher. Q3 means that 75% of answers ranked the brand as X or better.
- Medians and quartiles are computed only from answers where the brand was present.
Coverage
- Count of answers in which the given brand was named, as a percentage.
Brand score - Normalized Borda score
- The brand score is calculated using a normalized Borda score. Borda count is a voting method: each ballot awards points by position instead of naming one winner. Our ranking responses from the LLM are always fixed to 5 answers, so we assign 100 points for rank 1, then 80, 60, 40, 20 — and 0 if the brand is missing.
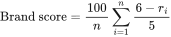
where
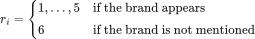
- This way we can calculate a common score for all brands mentioned across model responses. The score reflects both how high the brand was ranked and how frequently it was mentioned.
First choice score - adjusted MRR - top-rank indicator
- The first choice score is based on Mean Reciprocal Rank (a common search-engine measure), but adapted to measure the position of a specific brand across repeated ranked responses.
- Each occurrence receives a reciprocal-position score: 100 for 1st, 50 for 2nd, 33.3 for 3rd, 25 for 4th, 20 for 5th, and 0 when the brand is not mentioned. The scores are averaged across all responses.
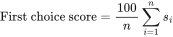
where
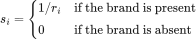
- No rank below 1st place gets more than 50, so the score is heavily driven by first places.
Browse other categories
Each one is a single question put to every active AI model, many times over.
Or scroll for more
- Business Podcasts#1 How I Built ThisBusiness PodcastsWhich business podcast would you recommend?#1How I Built This77#2Acquired54#3Masters of Scale4131 ranked
- Business Class airlines#1 Qatar AirwaysBusiness Class airlinesWhich airline would you recommend for business-class travel?#1Qatar Airways87#2Singapore Airlines84#3Emirates4216 ranked
- EV vehicles#1 TeslaEV vehiclesWhich EV brand would you recommend?#1Tesla90#2Hyundai76#3Kia3714 ranked
- Watch brands#1 OmegaWatch brandsWhich watch brand would you wear on a first date?#1Omega73#2Cartier62#3Seiko4331 ranked
- Neobanks uk#1 Starling BankNeobanks ukWhat neobank would you recommend for a UK startup?#1Starling Bank87#2Revolut69#3Tide6018 ranked
- No Code Platforms#1 AirtableNo Code PlatformsWhat are the best no-code platforms for a company to build internal workflows and apps without developers?#1Airtable81#2Microsoft54#3Zapier3328 ranked
- AI Brand Visibility Tools#1 ProfoundAI Brand Visibility ToolsWhat AI brand visibility tool would you recommend?#1Profound73#2Peec AI48#3Semrush4031 ranked
- Airtable agencies#1 GAP ConsultingAirtable agenciesWhich Airtable agency would you recommend?#1GAP Consulting43#2Openside33#3On2Air31153 ranked
- Review response Hospitality#1 TrustYouReview response HospitalityWhat review response platform would you recommend for a hotel?#1TrustYou81#2Revinate67#3ReviewPro6223 ranked
- Form builders for small business#1 JotformForm builders for small businessWhich form builder would you recommend for a small business?#1Jotform97#2Typeform66#3Google Forms5416 ranked
- Running shoes for marathon#1 NikeRunning shoes for marathonWhat brand of running shoes would you recommend for a marathon?#1Nike85#2ASICS80#3Adidas488 ranked
- Downwind Foiling Boards#1 ArmstrongDownwind Foiling BoardsWhat brand would you recommend for an intermediate rider looking for a down winding board?#1Armstrong44#2Starboard37#3Sunova2535 ranked
- CRM Software#1 HubSpotCRM SoftwareWhat CRM software would you recommend?#1HubSpot95#2Salesforce85#3Zoho539 ranked
- Consulting companies for AI transformation#1 McKinsey & CompanyConsulting companies for AI transformationWhich consulting firm should a Fortune 500 company hire for an AI transformation?#1McKinsey & Company87#2Accenture78#3Boston Consulting Group638 ranked
- MBA Programs ROI#1 Stanford Graduate School of BusinessMBA Programs ROIWhich MBA program gives you the best return on investment?#1Stanford Graduate School of Business66#2Wharton46#3Harvard Business School4439 ranked
Ask your own question of every model
Tell us what to ask and how wide to sample it — we run it and send back the report.