Your Brand has an AI reputation and it's shaping purchase decisions right now.
Swipe up to continue
What review response platform would you recommend for a hotel?
10 AI models · 10 answers per model · ranked by score
- Models
- 10
- Answers
- 100
- Brands named
- 23
What review response platform would you recommend for a hotel?
10 AI models · 10 answers per model · ranked by score
ordered by brand score: 100 pts for rank 1 → 20 for rank 5 · no mention = 0
- #1TrustYou81brand score70first choice12345
- #2Revinate67brand score49first choice
- #3ReviewPro62brand score43first choice
- #4Birdeye18brand score14first choice
- #5GuestRevu16brand score10first choice
Show 18 moreShow less
- #6Medallia9brand score6first choice
- #7Trustpilot8brand score8first choice
- #8Reputation6brand score5first choice
- #9MARA6brand score4first choice
- #10ReviewMeta5brand score3first choice
- #11Podium4brand score3first choice
- #12Yotpo4brand score2first choice
- #13Customer Alliance3brand score2first choice
- #14Google Reviews2brand score1first choice
- #15ReviewTrackers1brand score1first choice
- #16TripAdvisor1brand score1first choice
- #17Guestfolio1brand score1first choice
- #18Yelp1brand score1first choice
- #19Grade.us0brand score0first choice
- #20Reevoo0brand score0first choice
- #21Hootsuite0brand score0first choice
- #22Local Measure0brand score0first choice
- #23PowerReviews0brand score0first choice
Each bar covers the middle half of one model’s answers (Q1–Q3); the line inside it is that model’s median rank for the times it recommended the brand. The badge under a brand says how far apart the models are on it, and “first choice” scores rank 1 far above the rest — a brand can place well overall and still rarely lead an answer.
Swipe left for the full report
Brand by model
Median rank each model gave each brand.
Scroll the table sideways to see every model →
| claude-sonnet-5.5 | claude-opus-5.5 | gpt-6-luna | grok-4.7 | deepseek-v4.1-flash | gpt-6-astra | gemini-3.8-flash | qwen3.8-max | kimi-k3 | mistral-medium-3.5 | |
|---|---|---|---|---|---|---|---|---|---|---|
| TrustYou | 1.0 | 1.0 | 1.0 | 2.5 | 3.0 | 1.0 | 2.0 | 1.0 | 1.0 | 1.0 |
| Revinate | 2.0 | 2.0 | 3.0 | 1.0 | 2.0 | 3.5 | 1.0 | 3.0 | 2.0 | 3.0 |
| ReviewPro | 3.0 | 4.0 | 2.0 | 2.5 | 1.0 | 2.0 | 3.0 | 2.0 | 3.0 | 2.0 |
| Birdeye | 4.0 | 5.0 | 5.0 | 5.0 | — | 5.0 | 4.0 | 5.0 | 5.0 | 5.0 |
| GuestRevu | — | 4.0 | 4.0 | 4.0 | 4.0 | 4.0 | — | 4.0 | 4.0 | — |
| Medallia | — | 3.0 | 5.0 | 5.0 | — | — | 5.0 | — | — | — |
| Trustpilot | — | — | — | — | — | — | — | — | — | 1.0 |
| Reputation | 5.0 | — | 5.0 | — | 5.0 | — | 5.0 | 5.0 | 5.0 | — |
| MARA | — | — | 4.0 | — | — | 4.0 | — | — | 4.0 | — |
| ReviewMeta | — | — | — | — | — | — | — | — | — | 2.0 |
| Podium | 5.0 | — | — | 5.0 | — | — | 5.0 | 5.0 | 5.0 | 4.0 |
| Yotpo | — | — | — | — | — | — | — | — | — | 3.0 |
| Customer Alliance | — | — | — | — | 4.0 | 3.0 | — | — | — | — |
| Google Reviews | — | — | — | — | — | — | — | — | — | 2.0 |
| ReviewTrackers | — | — | — | — | 5.0 | — | — | — | — | — |
| TripAdvisor | — | — | — | — | — | — | — | — | — | 3.0 |
| Guestfolio | — | — | — | — | — | — | — | — | — | 4.0 |
| Yelp | — | — | — | — | — | — | — | — | — | 4.0 |
| Grade.us | — | — | — | — | — | — | — | — | — | 5.0 |
| Reevoo | — | — | — | — | — | — | — | — | — | 4.0 |
| Hootsuite | — | — | — | — | — | — | — | — | — | 5.0 |
| Local Measure | — | — | — | — | — | — | — | — | — | 5.0 |
| PowerReviews | — | — | — | — | — | — | — | — | — | 5.0 |
A dash means that model never named the brand in any of its runs. Deeper blue is better: rank 1 is the brand a model would recommend first.
Where the models disagree
4 of 23 brands split the panel. Each mark is one model's score for the brand, on the same 0–100 scale as the ranking.
- #2Revinate0100
mistral-medium-3.5 12 → grok-4.7 98
- #1TrustYou0100
mistral-medium-3.5 20 → gpt-6-astra 100
- #3ReviewPro0100
mistral-medium-3.5 16 → gpt-6-luna 86
- from here down, the models agree
- #6Medallia0100
claude-sonnet-5.5 0 → claude-opus-5.5 58 · 6 of 10 never named it
- #5GuestRevu0100
claude-sonnet-5.5 0 → qwen3.8-max 40 · 3 of 10 never named it
- #4Birdeye0100
deepseek-v4.1-flash 0 → claude-sonnet-5.5 40 · 1 of 10 never named it
A hollow mark is a model that never named the brand in any of its runs, which scores 0. Agreement is not endorsement — a brand every model ignores equally agrees just as tightly as one they all rank first.
Named, and named first
Across → how frequently the panel names the brand at all.
Up ↑ how often the answers that name it put it first.
- 1TrustYou91/62
- 2Revinate88/23
- 3ReviewPro86/15
- 4Birdeye65/0
- 5GuestRevu41/0
- 6Medallia22/0
- 7Trustpilot8/100
- 8Reputation23/0
The horizontal line sits at 20% — the rate a named brand would lead at if the models were picking one of its 5 slots at random. Above it they are choosing it first on purpose. Both figures average across models, so a thinly sampled model counts the same as a heavily sampled one.
What the models actually said
- Models
- 10
- Answers
- 100
TrustYou leads with a score of 81 of 100, ranked by 10 of 10 models.
Three hospitality-native platforms dominate this category, and every one of the 10 models ranks all three: TrustYou (brand score 81), Revinate (67.2) and ReviewPro (62.2). The next brand, Birdeye, falls to 18. The models broadly agree on which tools belong at the top. They disagree on the order, and one model, mistral-medium-3.5, largely works from a different list.
Who leads the top three
TrustYou is the most common default. claude-opus-5.5 and gpt-6-astra score it 100, and qwen3.8-max (98), claude-sonnet-5.5 (96) and kimi-k3 (94) come close behind.
Two models put Revinate first instead:
- grok-4.7 scores Revinate 98 and ranks it first in 9 of 10 runs.
- gemini-3.8-flash gives Revinate 88 against 84 for TrustYou.
deepseek-v4.1-flash breaks the pattern differently. It has ReviewPro at a median rank of 1 (score 82) and TrustYou at a median rank of 3 (score 60).
- 100gpt-6-astra40
- 98qwen3.8-max58
- 88gpt-6-luna64
- 100claude-opus-5.578
- 96claude-sonnet-5.576
- 94kimi-k384
- 20mistral-medium-3.512
- 84gemini-3.8-flash88
- 60deepseek-v4.1-flash74
- 70grok-4.798
TrustYou ahead on 7 of 10 models
The reasoning behind these swaps is mostly about framing rather than facts. All models credit the same features. The split is over whether TrustYou's analytics depth, or Revinate's CRM and guest-data breadth, counts for or against a platform meant mainly for replying to reviews.
gpt-6-astra is the clearest Revinate sceptic among models that name it consistently. It scores Revinate 40 and treats it as compelling mainly for properties already on the suite. claude-opus-5.5 is the harshest on ReviewPro, with a median rank of 4 and a score of 38.
Sources behind the top-three split
Hotel Tech Report is the most recalled source in the category. It is cited heavily by claude-sonnet-5.5, grok-4.7 and gemini-3.8-flash. Two of those three are the models that put Revinate first. Vendor websites lead for the most TrustYou-enthusiastic models: claude-opus-5.5, gpt-6-astra and qwen3.8-max.
It is a hypothesis, not something the data shows, that Hotel Tech Report coverage tilts models toward Revinate while vendor self-description tilts them toward TrustYou. claude-sonnet-5.5 also cites Hotel Tech Report heavily yet still ranks TrustYou first.
Single-model enthusiasms
Several brands owe almost all their score to one model:
- claude-opus-5.5 and Medallia. It ranks Medallia in all 10 runs (score 58), while only three other models name it, none above 14. Its sources lean on Medallia's own site plus G2 and Gartner. That fits an enterprise framing, but the causal link is hypothetical.
- gpt-6-astra and kimi-k3 on MARA (26 each), and gpt-6-astra on Customer Alliance (28). Both picks rest mostly on the vendors' own websites.
- deepseek-v4.1-flash on ReviewTrackers (14). It is the only model to name it.
Medallia · 58 points apart on a 0–100 scale
mistral-medium-3.5 as the outlier
mistral-medium-3.5 names TrustYou, Revinate and ReviewPro in only 2 of 10 runs each. When it does name TrustYou, it puts it first.
Its usual list is different. Trustpilot gets a score of 80 from mistral-medium-3.5, and no other model ranks it. mistral-medium-3.5 is also the only model to rank ReviewMeta (52), Yotpo (36), Google Reviews, TripAdvisor, Yelp, Guestfolio and Grade.us. Several of these are review destinations or e-commerce tools rather than hotel response platforms.
Its recalled sources match that shift. They include TechCrunch, Product Hunt, Moz, Search Engine Journal, Forbes and Business Insider, while hospitality trade sources appear only sparsely. That general-tech and SEO source mix plausibly explains its reading of the question, but this remains an inference.
Where models agree
The horizontal tools sit low with little disagreement. Birdeye scores 18, Reputation 6 and Podium 4.2. Each is described as capable but lacking OTA, PMS and benchmarking depth, and the supporting sources are mostly G2 and Capterra.
GuestRevu (16.2) also draws consistent mid-to-low placement, with a median rank of 4 from every model that names it. The long tail of Reevoo, Hootsuite, Local Measure and PowerReviews gets a single mention each.
What shaped the answers
63 sources across 1172 references, grouped by site from 187 recalled names. The top 5 carry 67% of them.
Sources are what each model recalled as having shaped its view. It does not mean that the sources were actually used in training. Recalled URLs might also be invalid or hallucinated.
hoteltechreport.com
- ×151/
- ×35named without a URL
- ×15/marketing/reputation-management
- ×8/marketing/reputation-management/trustyou
- ×6/marketing/reputation-management/reviewpro
- ×5/marketing/reputation-management/revinate
- ×5/
- ×3/marketing/guest-survey-tools
- ×3/marketing/reputation-management/revinate-guest-feedback
- ×1/company/medallia
- ×1/company/trustyou
- ×1/guest-experience/guest-feedback-software
- ×1/marketing/guest-feedback-surveys/revinate-surveys
- ×1/marketing/reputation-management-software
- ×1/marketing/reputation-management/reviewpro-guest-experience-platform
- ×1/marketing/reputation-management/reviewpro-guest-intelligence
- ×1HotelTechReport /operations/reputation-management/reviewpro
- ×1HotelTechReport /operations/reputation-management/revinate
- ×1HotelTechReport /operations/reputation-management/trustyou
- ×1/reputation-management/customer-alliance
- ×1/reputation-management/guestrevu
- ×1/reputation-management/reviewpro
- ×1/reputation-management/revinate
- ×1/reputation-management/trustyou
TrustYou
Summary
TrustYou scores strongly, with a brand score of 81 and a first choice score of 70.33. All 10 of the 10 models rank it, and several make it their default top pick: claude-opus-5.5 and gpt-6-astra each give it 100 and place it first in every run, while qwen3.8-max (98), claude-sonnet-5.5 (96) and kimi-k3 (94) are close behind. Still, per-model scores span 20 to 100 with a standard deviation of 23.97, which the report labels "models split." The low end comes from mistral-medium-3.5, which names TrustYou in only 2 of its 10 runs and scores it 20, though it puts it first both times. A softer tier also places it below the top spot. Grok-4.7 scores it 70 and deepseek-v4.1-flash scores it 60, and neither ranks it first in any run. Gemini-3.8-flash gives it 84 but ranks it first only twice.
per-model scores 20–100 of 100 · mean 81 across 10 models
The shared theme is that TrustYou is purpose-built for hospitality. Models point to its aggregation of OTA reviews, AI-assisted response drafting, sentiment and semantic analysis, and guest surveys. The models that rank it lower do not dispute these features. Instead, they frame TrustYou as more analytics- and review-intelligence-oriented than response-first. On that basis, grok-4.7, kimi-k3 and deepseek-v4.1-flash sometimes rank it behind Revinate or ReviewPro. Claude-sonnet-5.5 and gemini-3.8-flash add a second caveat: enterprise pricing and interface complexity may weigh on smaller or boutique properties. Hotel Tech Report underlies much of this reasoning. Claude-sonnet-5.5 cites it 10 times and grok-4.7 9 times, and gemini-3.8-flash cites a TrustYou-specific Hotel Tech Report page 8 times. TrustYou's own website is the most common source for the most enthusiastic models, including claude-opus-5.5, gpt-6-astra and qwen3.8-max. G2 and Capterra appear throughout as secondary references. Grok-4.7 is the only model that also draws on trade press such as PhocusWire and Skift.
“My strongest all-around recommendation for a hotel because it combines review management and AI-assisted responses with hospitality-focused guest-feedback analysis.”
“It ranks just behind Revinate because it is slightly more analytics-heavy and can feel less straightforward for a property that mainly needs fast replies.”
Per model summary
- claude-opus-5.5
- brand score
- 100
- first choice
- 100
- median rank
- 1.0
- present in
- 10/10
Consistently describes TrustYou as purpose-built for hospitality, aggregating reviews from OTAs like Booking.com, Expedia and TripAdvisor with AI-assisted response drafting and sentiment analysis. It frequently adds guest surveys, PMS integrations, and wide adoption by chains and independents.
- claude-sonnet-5.5
- brand score
- 96
- first choice
- 90
- median rank
- 1.0
- present in
- 10/10
Repeatedly frames TrustYou as hospitality-specific, combining review aggregation, response management, and guest surveys in one platform with AI-assisted responses and benchmarking. Some responses note it is enterprise-oriented and can be pricier or more complex for small properties.
- gpt-6-astra
- brand score
- 100
- first choice
- 100
- median rank
- 1.0
- present in
- 10/10
Consistently calls TrustYou its strongest all-around hotel recommendation. The stated reason is that it pairs hospitality-focused review management and AI-assisted responses with guest-feedback analysis that surfaces recurring service issues.
- gpt-6-luna
- brand score
- 88
- first choice
- 77
- median rank
- 1.0
- present in
- 10/10
Frames TrustYou mainly by its hospitality-specific focus on guest feedback and review management. Its ranking varies between first and behind ReviewPro, and it often advises checking integrations and response workflows against property needs.
- kimi-k3
- brand score
- 94
- first choice
- 85
- median rank
- 1.0
- present in
- 10/10
Stresses that TrustYou is purpose-built for hospitality, with broad OTA review aggregation, semantic analysis, and AI-assisted responses. It often cites wide adoption among hotel groups and PMS integrations, though some responses place it just behind Revinate for being more analytics-focused.
- mistral-medium-3.5
- brand score
- 20
- first choice
- 20
- median rank
- 1.0
- present in
- 2/10
Describes TrustYou as a hotel-specialized reputation management tool. It points to TrustYou aggregating reviews across platforms, integrating with major OTAs, and providing actionable insights to streamline responses.
- qwen3.8-max
- brand score
- 98
- first choice
- 95
- median rank
- 1.0
- present in
- 10/10
Usually ranks TrustYou first because it is built for hospitality and centralizes reviews from OTAs, Google, and surveys into one response workflow. It adds that sentiment analytics help hotel teams reply quickly and prioritize service issues.
- gemini-3.8-flash
- brand score
- 84
- first choice
- 60
- median rank
- 2.0
- present in
- 10/10
Emphasizes TrustYou as a hospitality benchmark that aggregates reviews from many sources and powers review summaries on booking and travel sites, with consolidated response dashboards. It often cautions that the broad feature set, interface complexity, or pricing can weigh on smaller boutique hotels.
- grok-4.7
- brand score
- 70
- first choice
- 42
- median rank
- 2.5
- present in
- 10/10
Portrays TrustYou as a long-standing hotel reputation platform known for meta-review scores, analytics, and benchmarking. It typically ranks it behind Revinate because it leans more toward review intelligence than toward being a fast, response-first reply console.
- deepseek-v4.1-flash
- brand score
- 60
- first choice
- 35
- median rank
- 3.0
- present in
- 9/10
Treats TrustYou as a mature hotel-focused option, typically ranked second or third, valued for review aggregation, sentiment analysis, and benchmarking. It is often placed behind ReviewPro or Revinate on response workflow or CRM breadth.
Sources per model
Each model’s own references for this brand, grouped by site. Tile area is that site’s share of the model’s references; tap one for the pages behind it.
hoteltechreport.com
trustyou.com
- ×6/
- ×1TrustYou Reputation Management /products/reputation-management
- ×1TrustYou Review Management /products/review-management
- ×1/solutions/hotel-reputation-management
- ×1/solutions/reputation-management
no URL recalled
- ×2named without a URL
hoteltechreport.com
Sources are what each model recalled as having shaped its view. It does not mean that the sources were actually used in training. Recalled URLs might also be invalid or hallucinated.
Revinate
Summary
Revinate earns a brand score of 67.2 and a first choice score of 49.42. Every one of the 10 models ranks it at least once, but they disagree sharply on how high, and the report labels it "models split." Per-model scores run from 12 to 98, with a standard deviation of 24.05. At the top, grok-4.7 scores it 98 and puts it first in 9 of 10 runs, and gemini-3.8-flash gives it 88 with six first-place rankings. kimi-k3 (84), claude-opus-5.5 (78), claude-sonnet-5.5 (76) and deepseek-v4.1-flash (74) form a solid second tier, usually placing it second. Both Claude models give it high scores but never rank it first. Lower down, gpt-6-luna gives 64, qwen3.8-max 58 and gpt-6-astra 40. mistral-medium-3.5 gives just 12, because it names Revinate in only 2 of 10 runs.
per-model scores 12–98 of 100 · mean 67 across 10 models
The split follows a single theme: Revinate is hospitality-native and tied to a broader CRM and guest-data suite. The higher-scoring models treat that as the core strength. They describe a shared inbox for Google, TripAdvisor and OTA reviews, with replies informed by guest profiles, PMS data and stay history. The lower-scoring models make the same observation and count it against the brand for this particular question. They argue the platform is broader, pricier or less review-specialized than a property needs if response is the only goal. kimi-k3 and qwen3.8-max explicitly place it behind TrustYou or ReviewPro on this basis. The recalled sources under both readings are largely the same set: Hotel Tech Report and G2 dominate for grok-4.7, gemini-3.8-flash and claude-sonnet-5.5, while Capterra appears more lightly. Revinate's own website is the leading citation for claude-opus-5.5, gpt-6-luna, gpt-6-astra and qwen3.8-max. Those models lean most heavily on the vendor's own framing of a broad guest-engagement platform.
“It is the strongest default recommendation because it matches how hotel staff actually handle reviews day to day.”
“I would prioritize it if your hotel already uses Revinate, but it is less compelling as a standalone purchase when review responses are your only need.”
Per model summary
- gemini-3.8-flash
- brand score
- 88
- first choice
- 77
- median rank
- 1.0
- present in
- 10/10
Emphasizes that Revinate is purpose-built for hospitality, linking review responses to guest profiles, PMS data, and sentiment analysis for personalized replies. Some reasonings mention higher pricing or that its full value depends on the broader CRM suite.
- grok-4.7
- brand score
- 98
- first choice
- 95
- median rank
- 1.0
- present in
- 10/10
Treats Revinate as the hospitality-native default, centering on a shared inbox for Google, TripAdvisor, and OTA reviews with reply workflows tied to guest messaging and surveys. Frequently calls it the strongest or first recommendation for most hotels.
- claude-opus-5.5
- brand score
- 78
- first choice
- 48
- median rank
- 2.0
- present in
- 10/10
Consistently describes Revinate as combining reputation management with a hotel CRM and email marketing, so review responses tie into guest data and direct-booking strategy. Often notes popularity with full-service, upscale, or branded properties.
- claude-sonnet-5.5
- brand score
- 76
- first choice
- 47
- median rank
- 2.0
- present in
- 10/10
Frames Revinate as a hotel-focused reputation tool with a unified review inbox, templates, and analytics, positioned within a wider guest data and email marketing suite. Several reasonings note it may be broader or pricier than a property needing only review replies.
- deepseek-v4.1-flash
- brand score
- 74
- first choice
- 60
- median rank
- 2.0
- present in
- 9/10
Repeatedly highlights Revinate's hotel-specific combination of review response, guest surveys, and CRM/guest data in one workflow, suited to multi-property groups. Rankings vary from first to third, with caveats that it may be more platform than small hotels need.
- kimi-k3
- brand score
- 84
- first choice
- 63
- median rank
- 2.0
- present in
- 10/10
Stresses Revinate's tight integration of review management with a hotel CRM and guest data platform, letting responses draw on guest profiles and stay history. Often places it just behind TrustYou, noting it is strongest when adopted with the broader ecosystem.
- gpt-6-luna
- brand score
- 64
- first choice
- 41
- median rank
- 3.0
- present in
- 10/10
Describes Revinate as connecting guest feedback and reviews with broader guest engagement and marketing. Usually ranks it around third because that wider scope may exceed what a hotel needs if review response is the main priority.
- mistral-medium-3.5
- brand score
- 12
- first choice
- 7
- median rank
- 3.0
- present in
- 2/10
Describes Revinate as a robust review and guest feedback platform with CRM integrations, while noting that its complexity and pricing may suit larger hotel chains more than smaller properties.
- qwen3.8-max
- brand score
- 58
- first choice
- 33
- median rank
- 3.0
- present in
- 9/10
Repeatedly frames Revinate as linking review response to guest CRM, email marketing, and pre/post-stay communication. Commonly ranks it second or third because it is broader and less review-specialized than TrustYou or ReviewPro.
- gpt-6-astra
- brand score
- 40
- first choice
- 23
- median rank
- 3.5
- present in
- 8/10
Consistently positions Revinate as best suited when review management fits into a broader guest-data and marketing strategy or when a hotel already uses Revinate. Typically ranks it below the top options for a response-only purchase.
Sources per model
Each model’s own references for this brand, grouped by site. Tile area is that site’s share of the model’s references; tap one for the pages behind it.
hoteltechreport.com
Sources are what each model recalled as having shaped its view. It does not mean that the sources were actually used in training. Recalled URLs might also be invalid or hallucinated.
ReviewPro
also named Shiji ReviewPro, ReviewPro (Shiji), Shiji
Summary
ReviewPro, which also appears as Shiji ReviewPro, earns a brand score of 62.2 and a first choice score of 43.03. All 10 of the 10 models rank it, but they place it very differently. Per-model brand scores run from 16 to 86 (standard deviation 20.89), and the report labels the brand "models split." Much of the low end comes down to visibility rather than verdict. mistral-medium-3.5 names it in only 2 of 10 runs, for a score of 16, even though it describes the Global Review Index favorably. At the top, gpt-6-luna scores it 86 and deepseek-v4.1-flash scores it 82, with deepseek-v4.1-flash putting it first in 5 runs. Most other models settle on second or third place, typically behind TrustYou or Revinate. claude-opus-5.5 has a median rank of 4 and scores it 38.
per-model scores 16–86 of 100 · mean 62 across 10 models
Across the models, the explanations share two themes. The positive one is that ReviewPro is purpose-built for hospitality, with Global Review Index benchmarking, multilingual response workflows and features suited to multi-property groups. The recurring caveat is that its analytics depth and enterprise orientation can feel heavier than a hotel needs if it mainly wants to respond to reviews. claude-sonnet-5.5 and gemini-3.8-flash cite pricing and a steeper learning curve, while kimi-k3 and claude-opus-5.5 describe its interface and pace of innovation as trailing newer rivals. The recalled sources behind these accounts are mostly ReviewPro's own site and Shiji's product pages, alongside Hotel Tech Report, G2 and Capterra. Grok-4.7 additionally cites trade outlets such as PhocusWire and Hospitality Net.
“I place it just behind TrustYou for a general recommendation, but its emphasis on operational analysis makes it especially worth considering for a hotel group.”
“Its interface and pricing can be heavier for small independent hotels.”
Per model summary
- deepseek-v4.1-flash
- brand score
- 82
- first choice
- 70
- median rank
- 1.0
- present in
- 9/10
Ranks Shiji ReviewPro first or second as a purpose-built hotel platform that aggregates OTA and survey feedback into one multilingual response workflow. It emphasizes sentiment analysis, benchmarking and PMS/CRM integrations suited to multi-property operations.
- gpt-6-astra
- brand score
- 80
- first choice
- 50
- median rank
- 2.0
- present in
- 10/10
Places ReviewPro just behind TrustYou and positions it as best for hotel groups needing reputation benchmarking and guest-experience reporting. It notes that this broader operational scope may be more than a small hotel focused on review responses needs.
- gpt-6-luna
- brand score
- 86
- first choice
- 65
- median rank
- 2.0
- present in
- 10/10
Calls ReviewPro a purpose-built, hotel-focused option for monitoring and responding to reviews, usually ranked just below TrustYou. It advises comparing integrations, channel coverage and workflows against the hotel's existing technology stack.
- mistral-medium-3.5
- brand score
- 16
- first choice
- 10
- median rank
- 2.0
- present in
- 2/10
Describes ReviewPro as a comprehensive hotel reputation suite covering monitoring, responses and analytics. It stresses that the widely recognized Global Review Index is useful for benchmarking performance.
- qwen3.8-max
- brand score
- 64
- first choice
- 43
- median rank
- 2.0
- present in
- 8/10
Typically ranks ReviewPro second as a hotel-native guest intelligence platform combining review response, sentiment analysis, benchmarking and case management. It notes that it can feel more enterprise-oriented and specialized than a simple response tool.
- grok-4.7
- brand score
- 72
- first choice
- 47
- median rank
- 2.5
- present in
- 10/10
Describes ReviewPro as a long-standing hotel reputation platform centered on competitive-set benchmarking and structured response workflows. It often ranks it behind Revinate because its analytics focus can feel heavier than a pure day-to-day response tool.
- claude-sonnet-5.5
- brand score
- 68
- first choice
- 47
- median rank
- 3.0
- present in
- 10/10
Frames ReviewPro as a long-established hospitality reputation platform with the Global Review Index, multilingual response tools and strong analytics. It consistently adds that the interface and pricing can feel heavy for small independent hotels.
- gemini-3.8-flash
- brand score
- 68
- first choice
- 47
- median rank
- 3.0
- present in
- 10/10
Highlights ReviewPro's hotel-specific guest intelligence, semantic analysis and departmental ticket routing that link reviews to operations. It repeatedly cites a steeper learning curve, setup complexity and enterprise pricing as drawbacks.
- kimi-k3
- brand score
- 48
- first choice
- 28
- median rank
- 3.0
- present in
- 8/10
Presents ReviewPro as an established hotel platform known for its Global Review Index and analytics, with benefits from the Shiji ecosystem. It consistently says its innovation pace and interface lag newer rivals, which places it mid-list.
- claude-opus-5.5
- brand score
- 38
- first choice
- 25
- median rank
- 4.0
- present in
- 9/10
Describes ReviewPro (part of Shiji) as a solid hospitality-specific option built around its Global Review Index benchmarking, response management and guest surveys. It repeatedly notes that its interface and AI features are seen as less modern than competitors.
Sources per model
Each model’s own references for this brand, grouped by site. Tile area is that site’s share of the model’s references; tap one for the pages behind it.
hoteltechreport.com
Sources are what each model recalled as having shaped its view. It does not mean that the sources were actually used in training. Recalled URLs might also be invalid or hallucinated.
Birdeye
also named BirdEye
Summary
Birdeye earns a brand score of 18 and a first choice score of 14.25. It is a consistent but low-placed recommendation: 9 of the 10 models rank it, yet none puts it first in any run. Its median rank is 4 for claude-sonnet-5.5 and gemini-3.8-flash and 5 for every other model. Per-model brand scores run from 0 to 40, with a standard deviation of 11.66, which the report labels broad agreement. The spread mostly reflects how often a model includes Birdeye rather than where it places it. claude-sonnet-5.5 (40), gemini-3.8-flash (34) and claude-opus-5.5 (22) name it in every run, while mistral-medium-3.5 names it in only 3 of 10 runs (6), and gpt-6-astra and gpt-6-luna name it in 5 of 10 (10 each).
per-model scores 0–40 of 100 · mean 18 across 10 models
The reasoning behind those placements barely varies. Models credit Birdeye's AI-assisted replies, multi-location management, listings tools and Google review handling. They then mark it down as a horizontal, industry-agnostic platform that lacks native PMS integrations, OTA-specific workflows for Booking.com, Expedia and TripAdvisor, and hotel benchmarking. Several models narrow its fit to particular buyers. claude-sonnet-5.5 suggests hotel groups wanting a unified tool, qwen3.8-max points to multi-property brands or simple independent needs, and mistral-medium-3.5 favours larger chains, citing cost and complexity. The sources the models recall are mostly general software-review aggregators, chiefly G2 and Capterra plus Software Advice, Trustpilot and Trustradius, along with Birdeye's own website. A hospitality-specific source, Hotel Tech Report, appears only once each under grok-4.7 and qwen3.8-max. That mix of sources fits the models' framing of Birdeye as a strong generalist rather than a hotel specialist.
“It is capable and flexible, but it lacks the hotel-specific benchmarking and OTA depth of the hospitality-focused tools.”
“The lack of native hospitality integrations and hotel-centric analytics makes it the weakest fit of the five for a hotel, even though it performs well in the broader market.”
Per model summary
- claude-sonnet-5.5
- brand score
- 40
- first choice
- 25
- median rank
- 4.0
- present in
- 10/10
Frames Birdeye as a general multi-location platform with strong AI-generated replies and broad site coverage that suits hotel groups wanting a unified tool, while lacking hotel-specific benchmarking and OTA depth.
- gemini-3.8-flash
- brand score
- 34
- first choice
- 24
- median rank
- 4.0
- present in
- 10/10
Credits Birdeye's AI-assisted response generation and multi-channel aggregation, but repeatedly points out that as a horizontal platform it lacks native hotel PMS and niche OTA integrations.
- claude-opus-5.5
- brand score
- 22
- first choice
- 21
- median rank
- 5.0
- present in
- 10/10
Describes Birdeye as a general multi-industry reputation platform with strong AI review responses and Google review management, but consistently notes it lacks the deep OTA integrations and hospitality-specific analytics of dedicated hotel tools.
- gpt-6-astra
- brand score
- 10
- first choice
- 10
- median rank
- 5.0
- present in
- 5/10
Consistently ranks Birdeye fifth as a capable option for centralized review management and AI-assisted responses, advising users to verify coverage of hotel booking and travel-review channels because it is less hospitality-specific.
- gpt-6-luna
- brand score
- 10
- first choice
- 10
- median rank
- 5.0
- present in
- 5/10
Presents Birdeye as a broader multi-location reputation platform with review monitoring and response tools, placing it fifth because it is less hotel-focused than the other options.
- grok-4.7
- brand score
- 20
- first choice
- 17
- median rank
- 5.0
- present in
- 8/10
Calls Birdeye a capable, widely used multi-location review-response platform strong on Google, but typically ranks it last because it is not hospitality-native and handles OTA workflows like Booking.com, Expedia, and TripAdvisor less natively.
- kimi-k3
- brand score
- 20
- first choice
- 16
- median rank
- 5.0
- present in
- 7/10
Acknowledges Birdeye as a strong, well-rated general reputation platform with AI-assisted responses and listings management, yet places it last because its industry-agnostic design lacks PMS integrations, OTA-specific handling, and hotel benchmarks.
- mistral-medium-3.5
- brand score
- 6
- first choice
- 6
- median rank
- 5.0
- present in
- 3/10
Positions Birdeye as a multi-location reputation tool better suited to larger hotel chains, citing its general business focus, complexity, and higher cost as drawbacks for smaller hotels.
- qwen3.8-max
- brand score
- 18
- first choice
- 15
- median rank
- 5.0
- present in
- 7/10
Describes Birdeye as a capable general reputation platform with review generation, monitoring, and response features, ranked lower because it is less tailored to hotel PMS, OTA, and guest-journey needs than hotel-first tools.
Sources per model
Each model’s own references for this brand, grouped by site. Tile area is that site’s share of the model’s references; tap one for the pages behind it.
Sources are what each model recalled as having shaped its view. It does not mean that the sources were actually used in training. Recalled URLs might also be invalid or hallucinated.
GuestRevu
Summary
GuestRevu sits in the middle tier for hotel review response, with a brand score of 16.2 out of 100 and a first choice score of 10.45. Seven of the 10 models ranked it, but none ever put it first. Every model that named it gave a median rank of 4, so the non-zero first choice score comes from partial credit for lower placements. Per-model brand scores run from 0 to 40, with a standard deviation of 13.98, which the report labels "broad agreement." Most of that spread reflects how often each model surfaced the brand rather than where it placed it. qwen3.8-max (40) and gpt-6-luna (34, at 90% coverage) named it most often, while claude-opus-5.5 included it in only one run and three models never ranked it.
per-model scores 0–40 of 100 · mean 16 across 10 models
The reasoning is consistent across models. GuestRevu is described as a hotel-specific tool pairing post-stay surveys with review monitoring and response, and as affordable and approachable for independent, boutique and small-group properties. It is held back by thinner enterprise integrations, analytics depth and market footprint than Revinate, TrustYou or ReviewPro. gpt-6-astra and kimi-k3 add a narrower point: they see its strength as broader guest feedback rather than response generation, which costs it ground on a response-first question. gpt-6-luna repeatedly hedges that integrations and channel coverage should be verified. The recalled sources behind these views are mainly GuestRevu's own website and Hotel Tech Report, with Capterra and G2 cited mostly by grok-4.7, qwen3.8-max and deepseek-v4.1-flash. grok-4.7 also cited SiteMinder, matching its note on GuestRevu's place in that ecosystem.
“It ranks fifth because its response automation and AI capabilities are less advanced than the platforms above, making it better as a feedback tool than a dedicated review response solution.”
“I rank it fourth because the fit is real, but its market footprint and depth are narrower than the platforms above.”
Per model summary
- claude-opus-5.5
- brand score
- 4
- first choice
- 3
- median rank
- 4.0
- present in
- 1/10
Describes GuestRevu as a hospitality-specific platform combining guest surveys and review monitoring with an approachable interface and pricing, suited to independent and boutique hotels wanting straightforward response workflows.
- deepseek-v4.1-flash
- brand score
- 20
- first choice
- 14
- median rank
- 4.0
- present in
- 6/10
Consistently frames GuestRevu as a hotel-specific surveys-plus-review-response tool well suited to independent, boutique, and small-group properties, ranked around fourth because its enterprise, integration, and multi-brand depth trail larger platforms.
- gpt-6-astra
- brand score
- 16
- first choice
- 12
- median rank
- 4.0
- present in
- 5/10
Repeatedly positions GuestRevu as a hotel-focused tool whose strength is broader guest-feedback and reputation management rather than response generation, which is why it ranks fourth or fifth for a response-first purchase.
- gpt-6-luna
- brand score
- 34
- first choice
- 22
- median rank
- 4.0
- present in
- 9/10
Treats GuestRevu as a relevant hospitality-focused feedback and reputation option but ranks it below others, repeatedly saying its integrations, channel coverage, and response workflows should be verified against the hotel's scale and needs.
- grok-4.7
- brand score
- 24
- first choice
- 15
- median rank
- 4.0
- present in
- 6/10
Presents GuestRevu as a practical, simpler hospitality tool combining post-stay surveys with review response for independent and smaller hotels, ranked fourth due to a narrower market footprint and less depth than Revinate, TrustYou, or ReviewPro.
- kimi-k3
- brand score
- 24
- first choice
- 15
- median rank
- 4.0
- present in
- 6/10
Emphasizes GuestRevu as an affordable, easy-to-use option pairing guest surveys with review monitoring that is popular with independent hotels and small groups, while noting it lacks the advanced AI, analytics, and integration breadth of larger platforms.
- qwen3.8-max
- brand score
- 40
- first choice
- 24
- median rank
- 4.0
- present in
- 8/10
Describes GuestRevu as a hotel-specific review aggregation and response platform suited to independent and smaller properties, typically ranked third or fourth because it may have fewer enterprise integrations and less analytics depth than the leaders.
Sources per model
Each model’s own references for this brand, grouped by site. Tile area is that site’s share of the model’s references; tap one for the pages behind it.
Sources are what each model recalled as having shaped its view. It does not mean that the sources were actually used in training. Recalled URLs might also be invalid or hallucinated.
How this was measured
The question
- Unaided brand recommendation question: “What review response platform would you recommend for a hotel?”
- The prompt asks each model to return exactly 5 brands, ranked 1 to 5, and for each one a reason for the recommendation and the sources that informed it.
Sampling
- Models are not deterministic, so the question is asked over and over — 10 answers per model
- Spellings of the same brand are normalized to the most commonly used form before counting
Measures of Position: Median and Quartiles
- Median value indicates that in 50% of answers the brand held this position or higher.
- Quartiles help visualize the spread of rankings per brand. Q1 indicates that 25% of answers had this rank or higher. Q3 means that 75% of answers ranked the brand as X or better.
- Medians and quartiles are computed only from answers where the brand was present.
Coverage
- Count of answers in which the given brand was named, as a percentage.
Brand score - Normalized Borda score
- The brand score is calculated using a normalized Borda score. Borda count is a voting method: each ballot awards points by position instead of naming one winner. Our ranking responses from the LLM are always fixed to 5 answers, so we assign 100 points for rank 1, then 80, 60, 40, 20 — and 0 if the brand is missing.
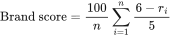
where
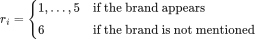
- This way we can calculate a common score for all brands mentioned across model responses. The score reflects both how high the brand was ranked and how frequently it was mentioned.
First choice score - adjusted MRR - top-rank indicator
- The first choice score is based on Mean Reciprocal Rank (a common search-engine measure), but adapted to measure the position of a specific brand across repeated ranked responses.
- Each occurrence receives a reciprocal-position score: 100 for 1st, 50 for 2nd, 33.3 for 3rd, 25 for 4th, 20 for 5th, and 0 when the brand is not mentioned. The scores are averaged across all responses.
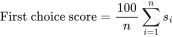
where
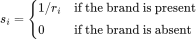
- No rank below 1st place gets more than 50, so the score is heavily driven by first places.
Browse other categories
Each one is a single question put to every active AI model, many times over.
- CRM Software#1 HubSpot
- Consulting companies for AI transformation#1 McKinsey & Company
- MBA Programs ROI#1 Stanford Graduate School of Business
- AI models for coding#1 Anthropic
- Business Podcasts#1 How I Built This
- Business Class airlines#1 Qatar Airways
- EV vehicles#1 Tesla
- Watch brands#1 Omega
See every category with its question and leaders.
Ask your own question of every model
Tell us what to ask and how wide to sample it — we run it and send back the report.